
By Gavin Stevens · Updated November 2026
Best Mac for running local LLMs
Unified memory is the whole story. How much you need, which of the late-2026 Macs (including the redesigned November MacBook Pro and the 512GB Mac Studio) gives you the most of it per dollar, and where the base M6 models fall short.
As an Amazon Associate I earn from qualifying purchases. Product links on this page go to Amazon; they are affiliate links, and the price you pay is the same.
The picks
 4TB
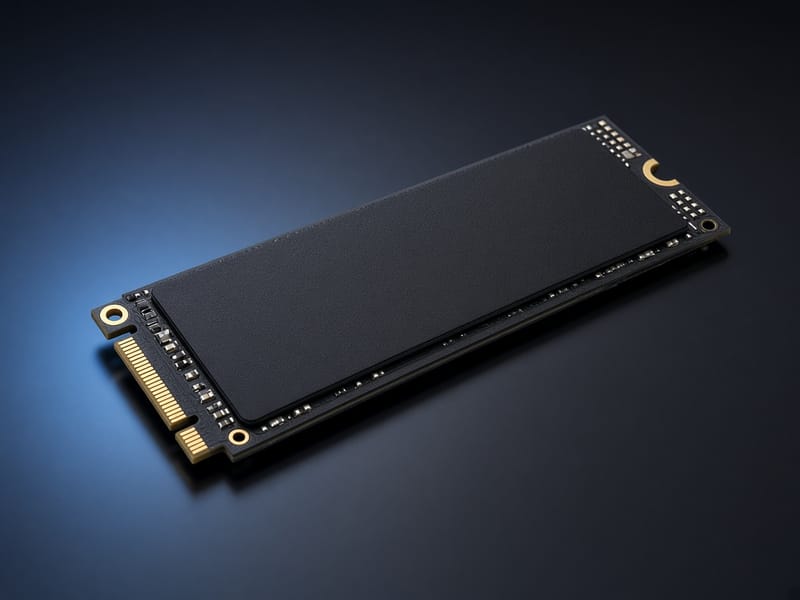
Samsung 990 PRO 4TB NVMe SSD (PCIe 4.0)
The drive for the enclosure next to it. 4TB holds a serious model library; PCIe 4.0 is all Thunderbolt can use anyway.
Same speed as the 2TB, twice the room. Cheaper than adding a second drive later.
 Thunderbolt
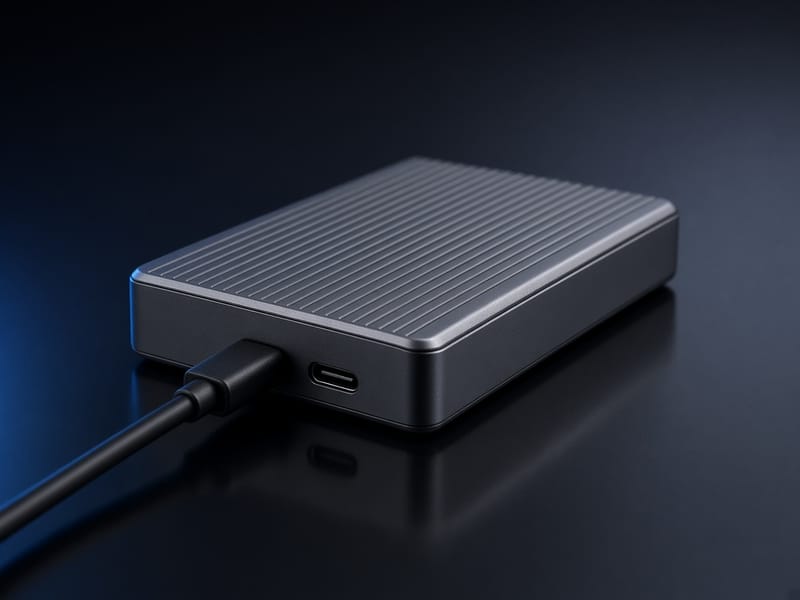
OWC Express 1M2 Thunderbolt NVMe enclosure (for Macs)
Buy the Mac with the base SSD and put your model library in this instead. Apple's storage upgrade prices are the one place not to spend.
Model load speed is disk-bound, and a Thunderbolt NVMe is fast enough that a 40GB model loads in seconds. Pair it with a 4TB drive.
 $1,000 to $3,000
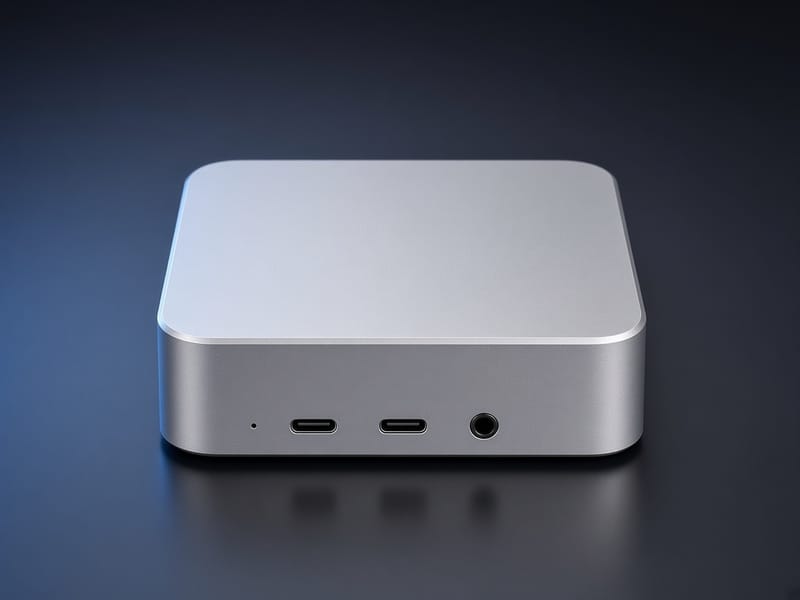
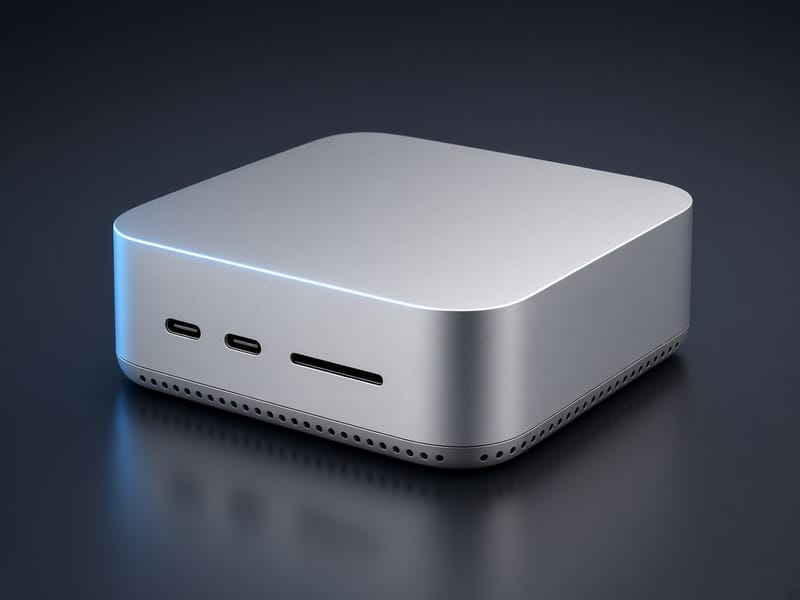
Mac mini (M5 Pro, 64GB unified memory)
Get 64GB; it's the top option on this chip and the floor for serious use. Runs 30B models well and 70B models badly, which is a fine place to start. No Mac under $1,000 has enough memory for this, so the lineup starts here.
Memory bandwidth on the M5 Pro is nearly double the base M6, and bandwidth is what decides tokens per second on a Mac.
 No ceiling
Mac Studio (M5 Max, 128GB unified memory)
128GB is the point where 70B models become everyday tools instead of experiments: 13 tokens a second on Llama 3.3 70B, 76 on gpt-oss-120B, measured. Most people should stop here.
The smallest quiet box that runs 70B models at a speed you'd use every day. The 128GB Strix Halo boxes fit the same models at less than half the bandwidth.
 No ceiling
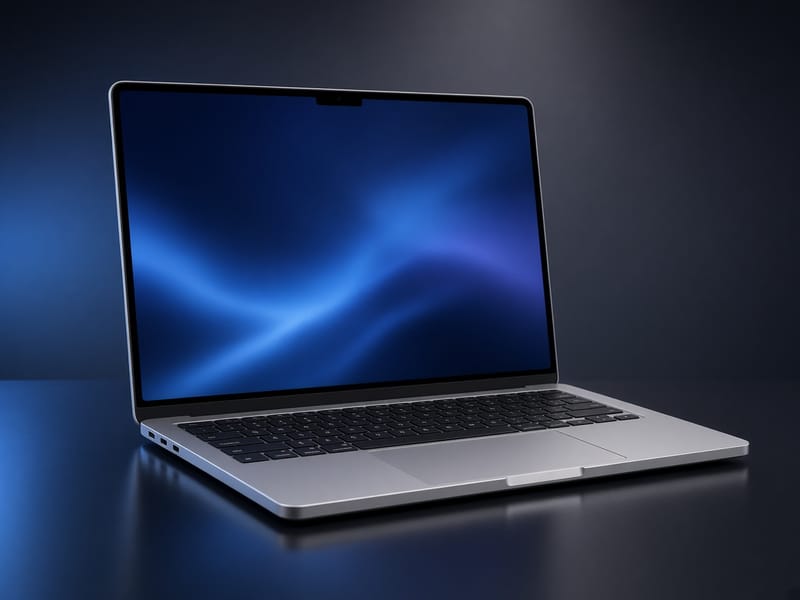
MacBook Pro 16-inch (M5 Max, 40-core GPU, 128GB unified memory)
Same memory and bandwidth as the Studio, portable. The redesigned OLED model shipped November 6 with the same M5 Max inside. Pick the 40-core GPU; the 32-core one has a quarter less bandwidth.
The fastest laptop for running a 70B model in memory. The 128GB Strix Halo and RTX Spark laptops fit the same models at well under half the bandwidth. It will be loud and warm doing it, and it will do it on a plane.
No ceiling Mac Studio (M5 Ultra, 256GB or 512GB unified memory)
512GB loads the largest open models that exist. On sale since October 28 at $22,299 for the 512GB configuration. If you don't already know you need this, you don't.
Up to 512GB of unified memory at 1.2TB/s. If you want to run the biggest open models locally, this is the one box that does it.
Why a Mac at all
On a PC, a model has to fit in the graphics card’s memory or it crawls. Consumer cards top out at 24 to 32GB, and in 2026 the 24GB ones are used-market cards. On Apple Silicon the CPU and GPU share one pool of memory, so a Mac with 128GB holds a model no consumer graphics card can. That’s the entire argument, and for inference (running models, not training them) it’s a strong one.
What actually matters
Unified memory size. A model’s size on disk is roughly its size in memory. A 30B-parameter model at 4-bit quantization is about 18GB; a 70B model is about 40GB; the OS and your apps want 10 to 15GB on top. Buy memory for the models you’ll run next year, not this month.
Memory bandwidth. This decides tokens per second. On the current chips: base M6 is 170GB/s (on the 24GB and 32GB configurations; the 16GB one is slower), M5 Pro is 307GB/s, M5 Max is 460GB/s with the 32-core GPU and 614GB/s with the 40-core, M5 Ultra is 1.2TB/s. Measured on a 128GB Mac Studio M5 Max: Llama 3.3 70B at 13 tokens a second, Qwen3 32B at 25, gpt-oss-120B at 76. A 70B model on a Pro chip runs; on a Max it runs at a speed you’d actually use.
Not the CPU core count, not the SSD. Both are fine on every current Mac. Spend the money on memory.
Configure-to-order. The memory sizes that matter here (64GB on the mini, 128GB on the Max machines, 256GB and up on the Ultra) are build-to-order options at apple.com. Amazon stocks the standard configurations, so the links on this page may land on a smaller-memory model; check the memory line before you buy.
What doesn’t work
- Base M6 Mac mini. Tops out at 32GB and 170GB/s. Runs 8B and 14B models nicely and stops there. Fine for trying Ollama, not for a daily driver.
- MacBook Air. Same chip class as the base mini, worse thermals. It throttles under sustained load, which is what inference is.
- 14-inch MacBook Pro with the base M6. Announced October 27, shipping November 6, 32GB ceiling, same story as the mini. It’s the cheapest MacBook Pro and it’s the wrong one for this. The M5 Pro and M5 Max models are a different machine; see below.
- Intel Macs. No.
MacBook Pro
Apple redesigned the 14- and 16-inch MacBook Pro in October 2026: a tandem OLED touchscreen it calls PROLED XDR, up to 16TB of storage, and the same M5 Pro and M5 Max chips as before, up to 128GB. It shipped November 6. For running models nothing changed: the M5 Max version takes the same 128GB and 614GB/s as the Mac Studio M5 Max, which makes it the fastest laptop for running a 70B model in memory. The 128GB Strix Halo laptops and the RTX Spark laptops fit the same models at less than half the bandwidth (256 and 283GB/s measured). Two cautions: pick the 40-core GPU (the 32-core version drops to 460GB/s), and expect fans and heat under sustained load. The M5 Pro MacBook Pro at 64GB is a fair substitute for the Mac mini M5 Pro if you need the keyboard attached. If the previous-generation design is still in stock at a discount, it’s the same chip and the same speed.
Storage: don’t buy it from Apple
Models are big and Apple’s internal storage upgrades cost several times what the same capacity costs anywhere else. Buy the base SSD, then put a 4TB NVMe in a Thunderbolt enclosure. You get about 3GB/s, which loads a 40GB model in seconds, and the drive moves to your next Mac. Keep the OS and apps internal; models, datasets and caches go external.
Software to pair it with
Ollama for the command line, LM Studio for a GUI, and MLX if you want Apple’s own framework. All three use the GPU through Metal out of the box; nothing to configure.
Sources
Related guides
DGX Spark vs Mac Studio vs Strix Halo: the three 128GB desktop boxes
Three small, quiet desktops hold a 70B model in memory. Measured now: the Mac runs a dense 70B three times faster than the other two and a 120B mixture-of-experts about a third faster. The DGX Spark went to $6,950 in October. Which one for running models, which for building on them, and which to skip.
Surface Laptop Ultra vs MacBook Pro M5 Max for local AI
Two laptops hold 128GB of unified memory, and both have been measured now. The Surface's bandwidth is 283GB/s against the Mac's 614, the Surface has CUDA and the Mac doesn't, and Apple's redesigned MacBook Pro ships with the same M5 Max. Which to buy in November 2026.
Run AI locally or in the cloud? Which jobs belong on your computer and which belong with ChatGPT or Claude
Local LLM vs cloud AI: a model on your own machine is a fixed effort budget, right for drafts, code first passes and anything you'll review, wrong for security review and hidden edge cases. How to split the work between local and ChatGPT, Claude or the API, with the benchmark data behind the line.